ARISE

From Social Reasoning to Embodied Interaction:
An Agentic Framework for Social Robots

Anonymous Authors

Agentic Reasoning and Interactive Social Embodiment

arXiv link coming soon.

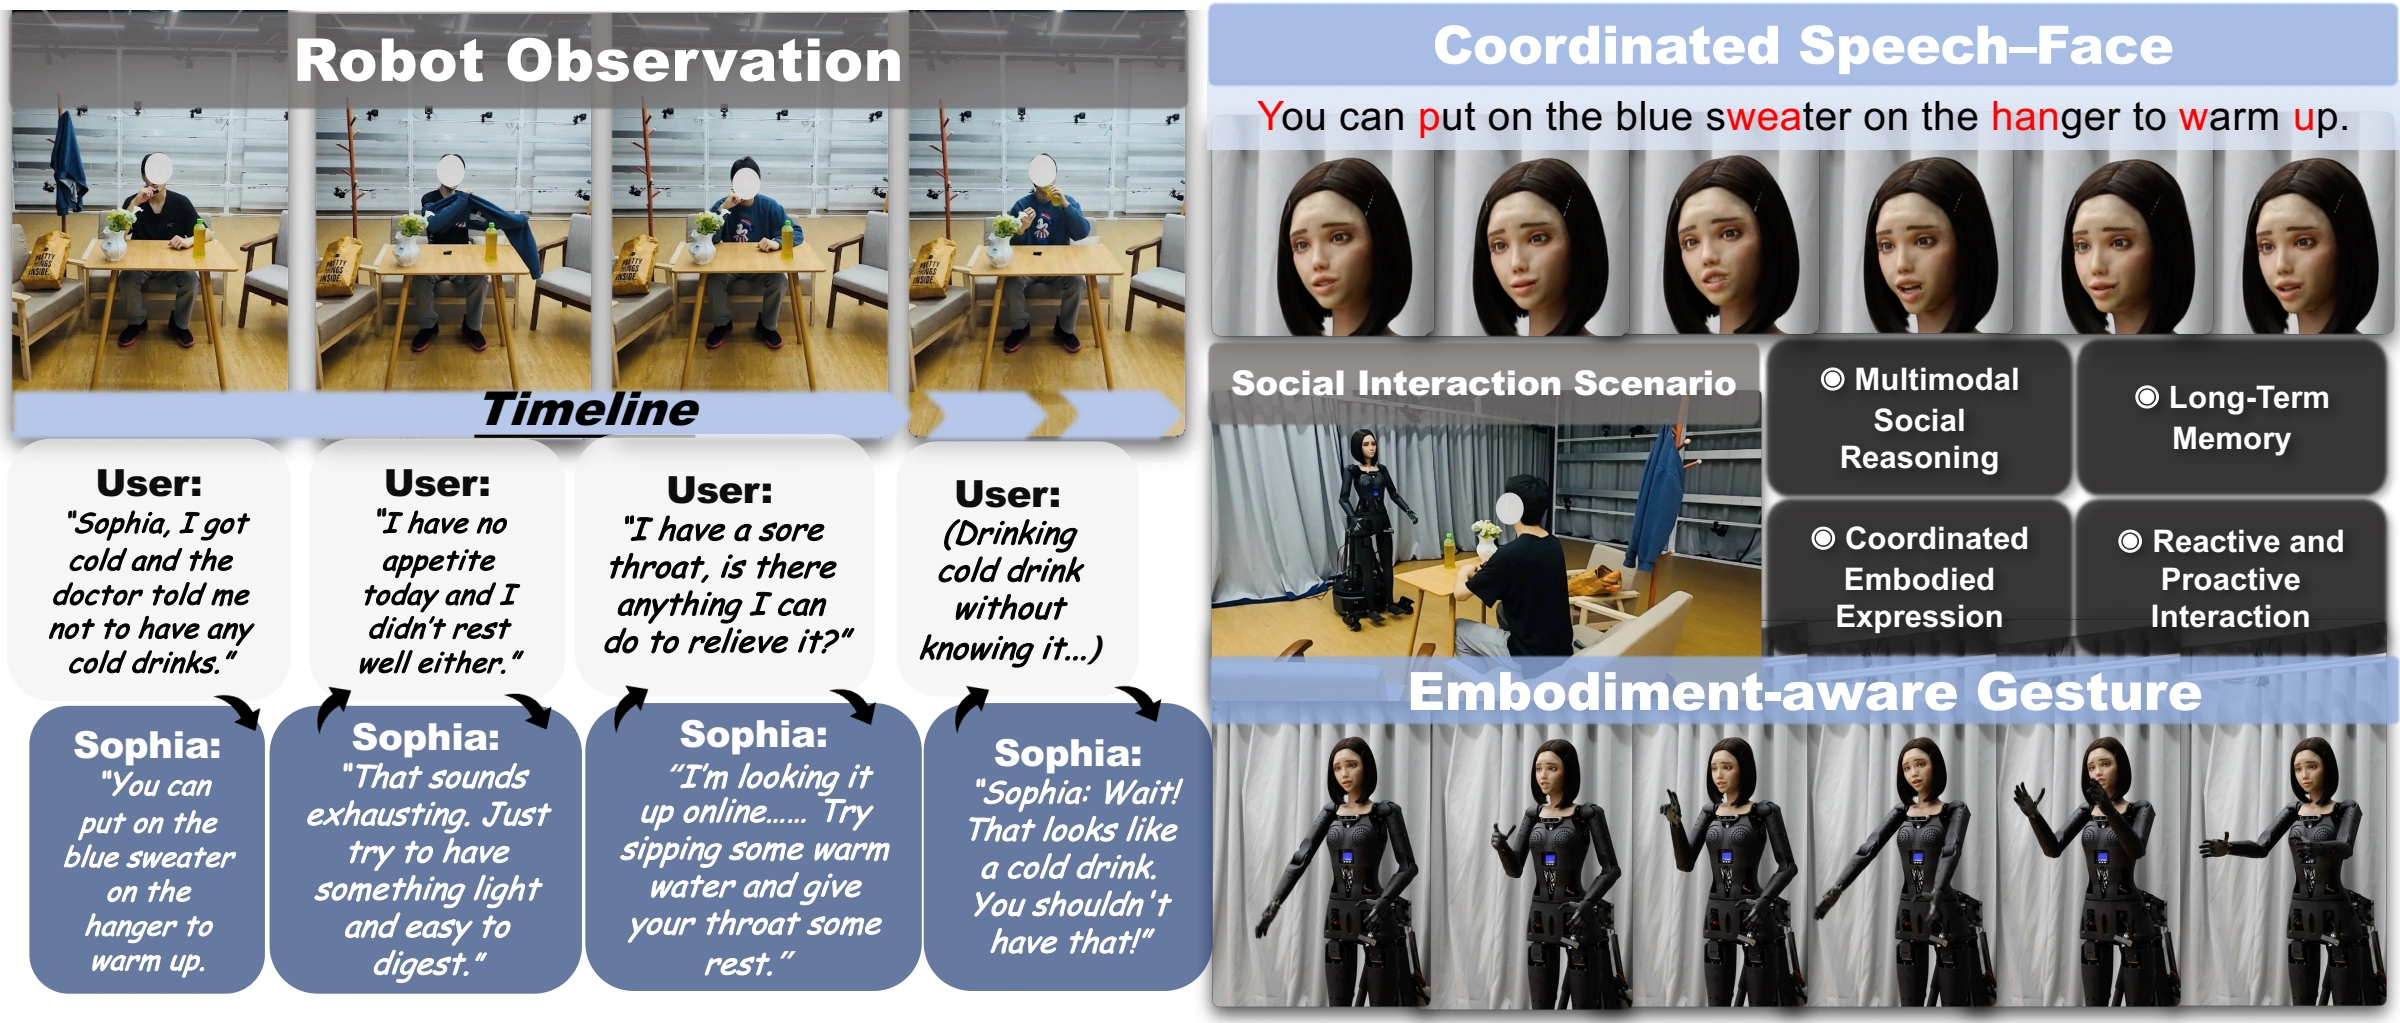
ARISE on Sophia: multi-round observations and dialogue alongside coordinated speech, facial expressions, and robot-native gestures.
From social intent to coordinated robot behavior. ARISE connects multimodal understanding, long-term memory, and proactive engagement with expressive speech, face, and gesture execution on Sophia.

Abstract

Natural face-to-face human–robot interaction requires a robot to understand an evolving social situation, decide when to engage, and express its intent through coordinated physical behavior. Yet existing approaches rarely close this loop: foundation-model agents provide increasingly capable multimodal reasoning and memory but remain largely disembodied, while expressive virtual agents do not face the physical constraints of real robots, and physical social robots typically address social reasoning and embodied expression only partially.

We present ARISE, a unified framework that bridges Agentic Reasoning and Interactive Social Embodiment on the Sophia humanoid robot. ARISE integrates multimodal context understanding, long-term memory, and reactive and proactive interaction to determine when and what to communicate, and translates social intent into robot-native gestures coordinated with speech and mechanical facial expressions through streaming execution.

Extensive evaluations on Sophia demonstrate strong perceived interaction quality, expressive and well-coordinated embodied behavior, and substantial latency reductions through streaming execution. These results highlight the importance of jointly reasoning about what to communicate, when to engage, and how to physically express social intent for natural interaction with humanoid robots.

Overview
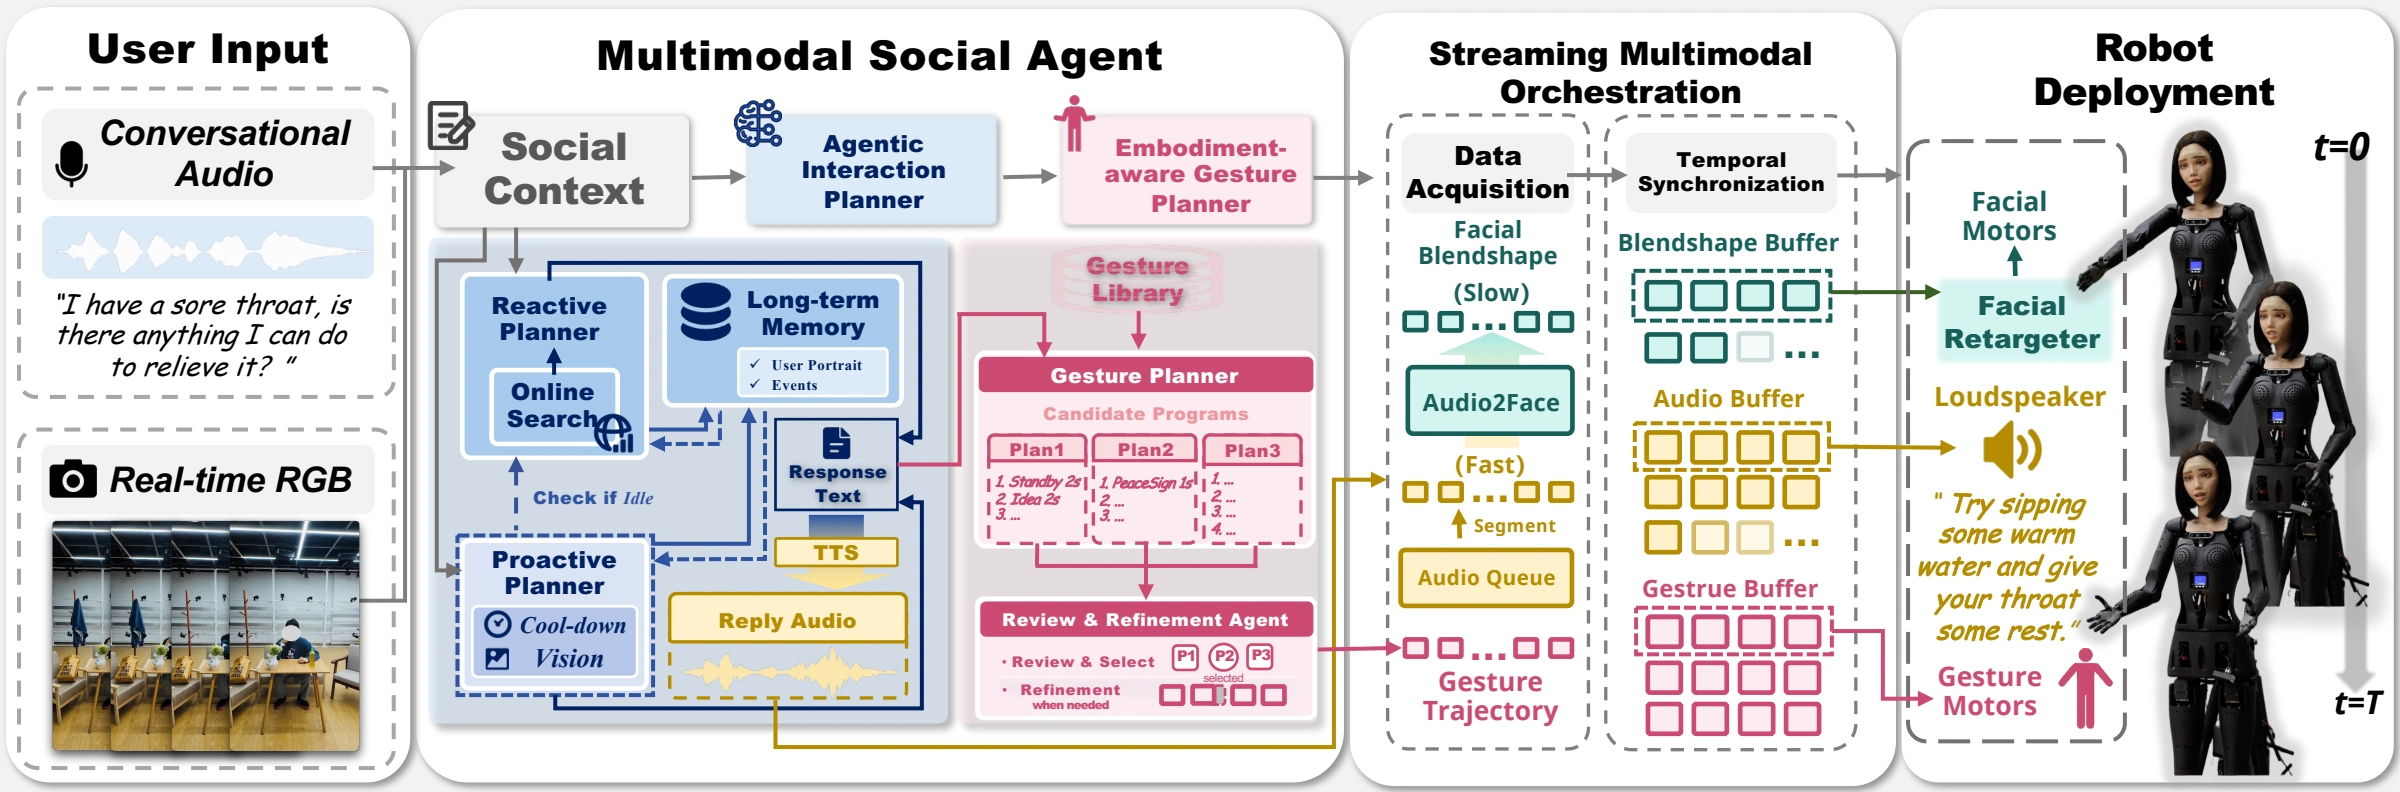
ARISE pipeline: conversational audio and RGB observations enter a multimodal social agent, followed by streaming multimodal orchestration and deployment to Sophia's facial motors, loudspeaker, and gesture motors.
ARISE framework. The Multimodal Social Agent determines what and when to communicate. Streaming Multimodal Orchestration synchronizes speech, facial animation, and gestures for progressive execution. Robot Deployment maps each output to Sophia’s actuators.

Visualization Results

Birthday Gift

Birthday gift. Across multiple interaction turns, Sophia keeps a surprise gift confidential and recalls its location when asked by the original user.

Whose Bag

Whose bag. Sophia combines visual observations with memory of earlier interactions to associate belongings with their owners.

Clean Up Desk

Clean up desk. Sophia provides visually grounded guidance, proactively acknowledges progress, and suggests an appropriate place for the user's laptop.